Building reliable LLM applications takes more than collecting a pile of raw text. Teams need to parse documents, extract consistent fields, review model outputs, compare prompts, and keep sensitive data under control. That is why people searching for what are top llm data annotation tools often find a broader category than classic point-and-click labeling software. This guide compares 10 tools that support the surrounding workflow, from local document analysis and structured extraction to evaluation and private deployment. The list is useful when you are building training data, preparing retrieval corpora, or validating an LLM system before it reaches customers.
Start here
There is no single winner for every annotation project. The right choice depends on whether you need a developer framework, a document workspace, an evaluation harness, or infrastructure that keeps data inside your environment.
Best overall match: AnythingLLM for teams that want local document chat, RAG, agents, and model flexibility in one desktop application.
Best for structured enterprise knowledge: LlamaIndex when parsing, extraction, and knowledge assistants matter more than a visual labeling interface.
Best for document-heavy review: DocumentLLM for legal and operations teams working across multiple files.
Best for schema-driven extraction: JsonLLM when annotations need to become clean JSON and usable APIs.
Best for evaluation: LLM Tester when your priority is repeatable conversational testing and analytics.
Best for private infrastructure: ThirdAI for organizations that need air-gapped deployment and CPU-based operation.
A quick warning before you shortlist: these products are adjacent to traditional annotation platforms rather than a uniform set of labeling consoles. They become particularly useful when "annotation" means preparing documents, defining schemas, generating test cases, checking extracted fields, or curating knowledge for an LLM application.
Segment comparison
| Segment | What it helps you do | Strongest fit | Tools to inspect |
|---|---|---|---|
| Local knowledge and RAG | Keep documents private while building retrieval workflows | Developers and privacy-conscious teams | AnythingLLM, llmchat.co |
| Parsing and structured extraction | Turn PDFs and unstructured files into usable fields | Analysts and data teams | LlamaIndex, JsonLLM |
| Document review | Inspect, compare, and discuss multiple documents | Legal and research teams | DocumentLLM |
| Deployment and integration | Connect models to applications with less infrastructure work | Developers and enterprises | ThirdAI, LLM-X.AI |
| Testing and comparison | Evaluate conversational behavior and model differences | AI builders and QA teams | LLM Tester, LLM Clash |
Shortlist paths
Use these paths to avoid comparing fundamentally different products on the wrong criteria.
| Your immediate need | Start with | Why |
|---|---|---|
| Annotate or inspect private documents locally | AnythingLLM | It combines a built-in LLM, RAG, and agents without requiring an account for the free desktop experience. |
| Build a production knowledge assistant | LlamaIndex | Its parsing, extraction, and knowledge-management features fit a pipeline rather than a one-off review. |
| Extract stable fields from PDFs | JsonLLM | JSON-schema API creation gives the output a defined shape. |
| Test whether an LLM workflow actually works | LLM Tester | Automated evaluations, analytics, and custom scenarios make repeatable checks easier. |
| Keep deployment air-gapped | ThirdAI | It focuses on private deployment and CPU-based GenAI operation. |
Ranking snapshot
Scores reflect the practical match for LLM data preparation and adjacent annotation workflows, not a claim that every product is a conventional labeling platform.
| Rank | Tool | Score | Best for | Starting price |
|---|---|---|---|---|
| #1 | AnythingLLM | 93/100 | Developers | Check vendor pricing |
| #2 | LlamaIndex | 92/100 | Financial analysts | Free: $0 |
| #3 | llmchat.co | 90/100 | Researchers | Check vendor pricing |
| #4 | DocumentLLM | 89/100 | Legal professionals | Free |
| #5 | JsonLLM | 89/100 | Data scientists | Check vendor pricing |
| Rank | Tool | Score | Best for | Starting price |
|---|---|---|---|---|
| #6 | ThirdAI | 89/100 | Enterprises | Check vendor pricing |
| #7 | LLM Farm | 89/100 | AI developers | Check vendor pricing |
| #8 | LLM-X.AI | 88/100 | Software developers | Check vendor pricing |
| #9 | LLM Tester | 88/100 | AI developers | Basic: $59 per month |
| #10 | LLM Clash | 88/100 | AI enthusiasts | Check vendor pricing |
How we grouped and ranked the list
The ranking starts with workflow usefulness, not the loudest feature list. A tool earned a stronger position when its documented capabilities could support a real data-preparation loop: bring in source material, transform or organize it, inspect the result, and use that result in an LLM application or evaluation process.
We grouped the tools into five practical segments: private local workspaces, parsing and extraction frameworks, document analysis, deployment and API infrastructure, and evaluation or model comparison. That grouping matters because a developer choosing an annotation-adjacent framework should not judge it by the same standard as a legal reviewer choosing a document canvas.
We also considered audience fit, implementation friction, privacy posture, stated free access, and market signal. Usage is a supporting signal rather than a quality guarantee. For example, AnythingLLM has a much stronger traffic signal than several specialist tools, while LLM Tester may still be the more relevant choice for a team that needs automated evaluation. Pricing remains a moving target, so verify current quotas and plan limits before committing.
Ranked field notes
1. AnythingLLM

- Developers building private document and RAG workflows
- Free desktop app; document chat and agents; no account needed
- Starts at Check vendor pricing
- Usage signal: 453.6K
Why it matters
AnythingLLM is the most balanced choice when your annotation process starts with source documents rather than a prebuilt labeling queue. Its built-in LLM, RAG support, and AI agents let a developer load material, interrogate it, and organize a knowledge workflow locally. That local-first angle is especially useful for sensitive research or internal documents. It is not a dedicated span-labeling suite, but it can cover a meaningful part of the preparation and review loop without sending every file to a hosted service.
Best for
Developers prototyping private document-grounded applications
Teams that want RAG and agents in the same workspace
Users who need custom or enterprise models alongside a local setup
Limitations
You must download and install a desktop application
Self-hosting or cloud deployment may require technical knowledge
It is a broader AI workspace, not a specialized annotation console
Shortlist signal: Add AnythingLLM when privacy, local document work, and fast RAG prototyping matter more than formal label-management features.
2. LlamaIndex

- Financial analysts building knowledge assistants
- Free 10K credits; knowledge assistants; parsing from $50/month
- Starts at Free: $0
- Usage signal: 323.6K
Why it matters
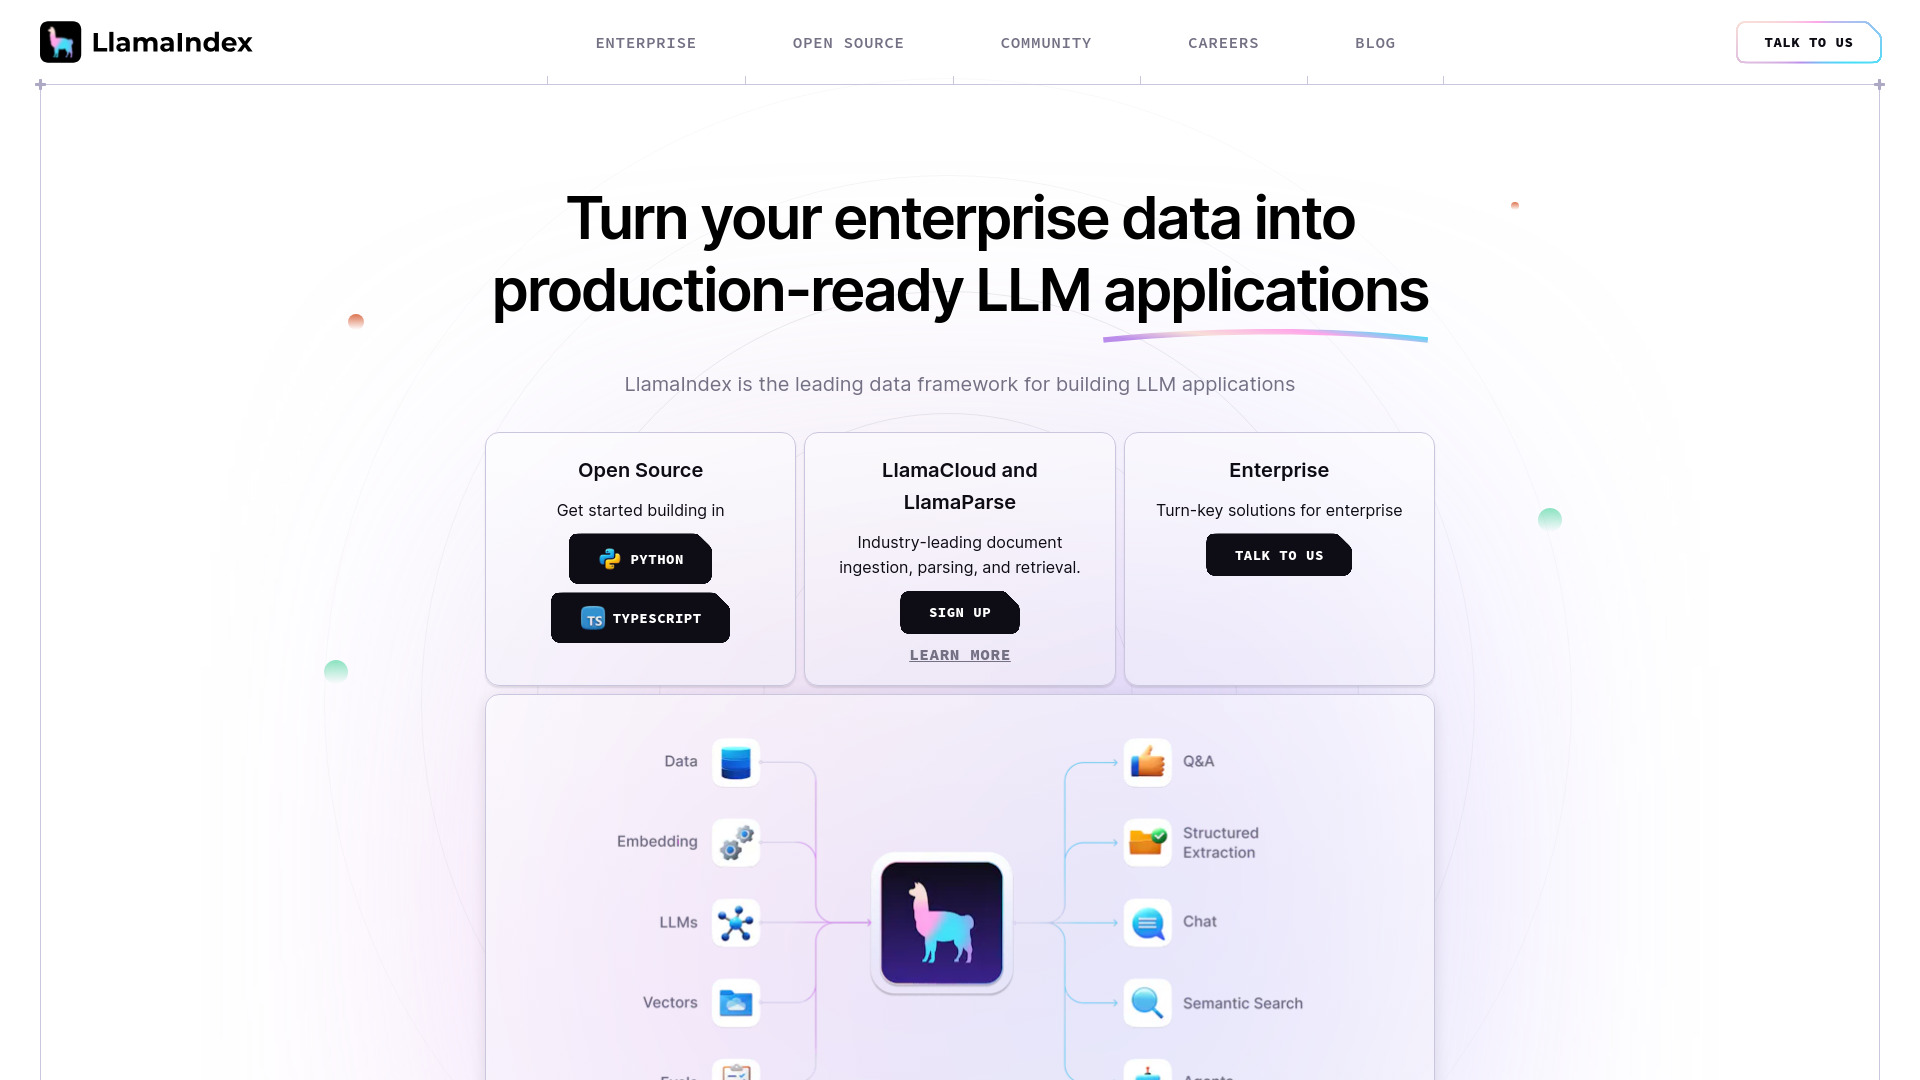
LlamaIndex makes the strongest case for treating data annotation as a pipeline problem. LlamaParse handles document parsing, LlamaExtract targets data extraction, and the broader platform supports knowledge management. That combination is valuable when you need repeatable transformations rather than manual review alone. Teams can move from messy documents to a knowledge assistant with a clearer path to production, although the framework demands more technical ownership than a simple visual workspace.
Best for
Analysts and developers turning enterprise documents into structured knowledge
Teams prototyping and deploying RAG applications
Workflows that need document parsing and extraction as separate steps
Limitations
Data pipelines can be complex to configure
Customization and optimization require technical expertise
Credit-based usage and paid tiers need careful budgeting
Shortlist signal: Choose LlamaIndex when your annotation work must become a maintainable parsing, extraction, and RAG pipeline.
3. llmchat.co

- Researchers running private AI-assisted research
- Free plan available
- Starts at Check vendor pricing
- Usage signal: 215
Why it matters
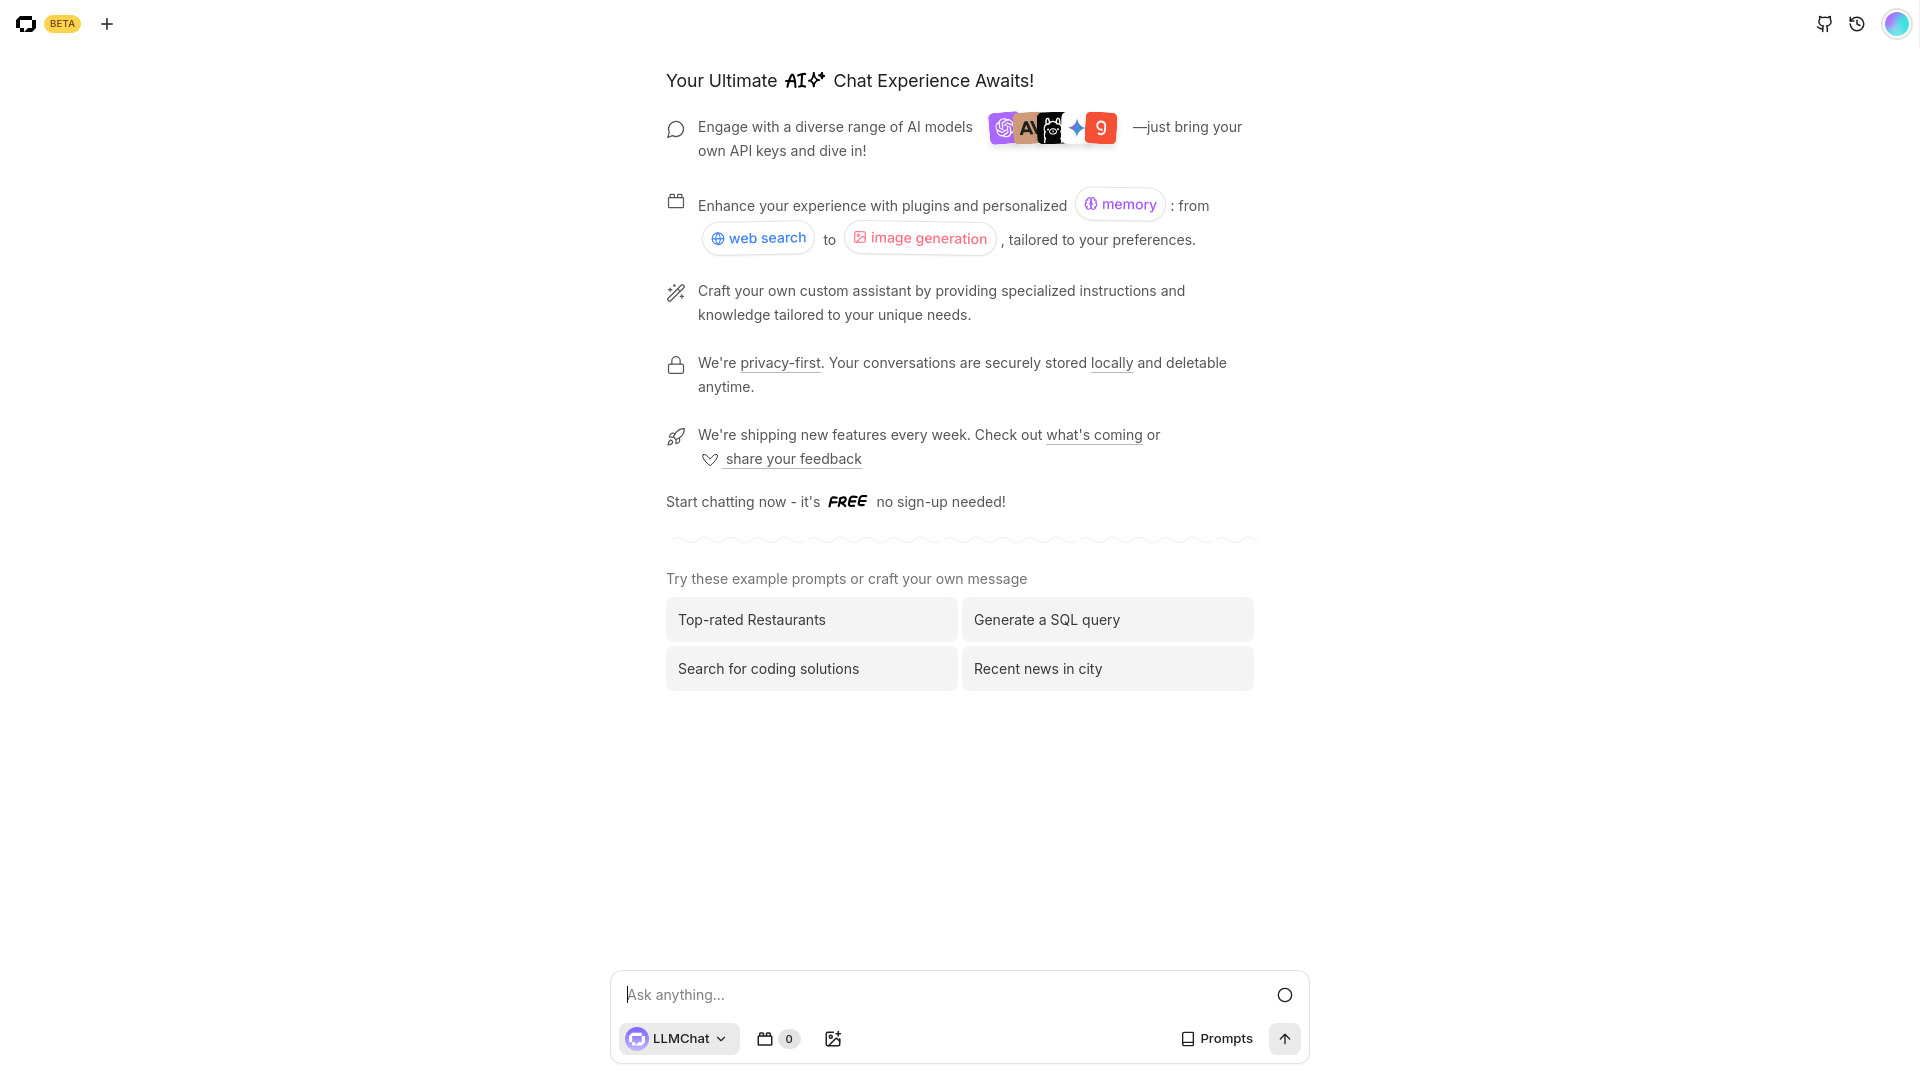
For researchers, llmchat.co brings a useful combination of AI-powered research, agentic workflows, and privacy-focused chat. Its open-source positioning gives technically comfortable users more visibility into how the tool works and more room to adapt it. That makes it a reasonable companion for reviewing source material or exploring annotation guidelines before formalizing them elsewhere. The small usage signal suggests a narrower product footprint, but that is not automatically a problem for an early-stage or privacy-sensitive workflow.
Best for
Researchers exploring agentic document and knowledge workflows
Users who want chat history to remain on the device
Open-source-minded teams that value transparency and modification
Limitations
There is no mobile version yet
MCP compatibility and usage tracking are still listed as coming soon
It may require more self-direction than a mature enterprise platform
Shortlist signal: Include llmchat.co when local privacy and open-source flexibility outweigh broad platform maturity.
4. DocumentLLM

- Legal professionals reviewing document sets
- 10 document uploads free; multi-document chat
- Starts at Free
- Usage signal: Not listed
Why it matters
DocumentLLM is the most immediately approachable option for teams that need to inspect documents before turning findings into training or evaluation data. AI-powered document analysis, an interactive document canvas, and multi-document chat are a practical combination for comparing files and extracting recurring information. Legal professionals are the clearest fit, but operations and research teams may also appreciate the review-oriented workflow. The key trade-off is that convenience does not remove the need to verify model output.
Best for
Legal teams comparing and interrogating multiple documents
Reviewers who prefer an interactive canvas over a developer framework
Small projects that can begin with 10 free document uploads
Limitations
Unlimited access may require a subscription
AI extraction and analysis still need human verification
It is designed around document analysis rather than full annotation governance
Shortlist signal: Pick DocumentLLM when human reviewers need a clear workspace for multi-document analysis before labels or fields are finalized.
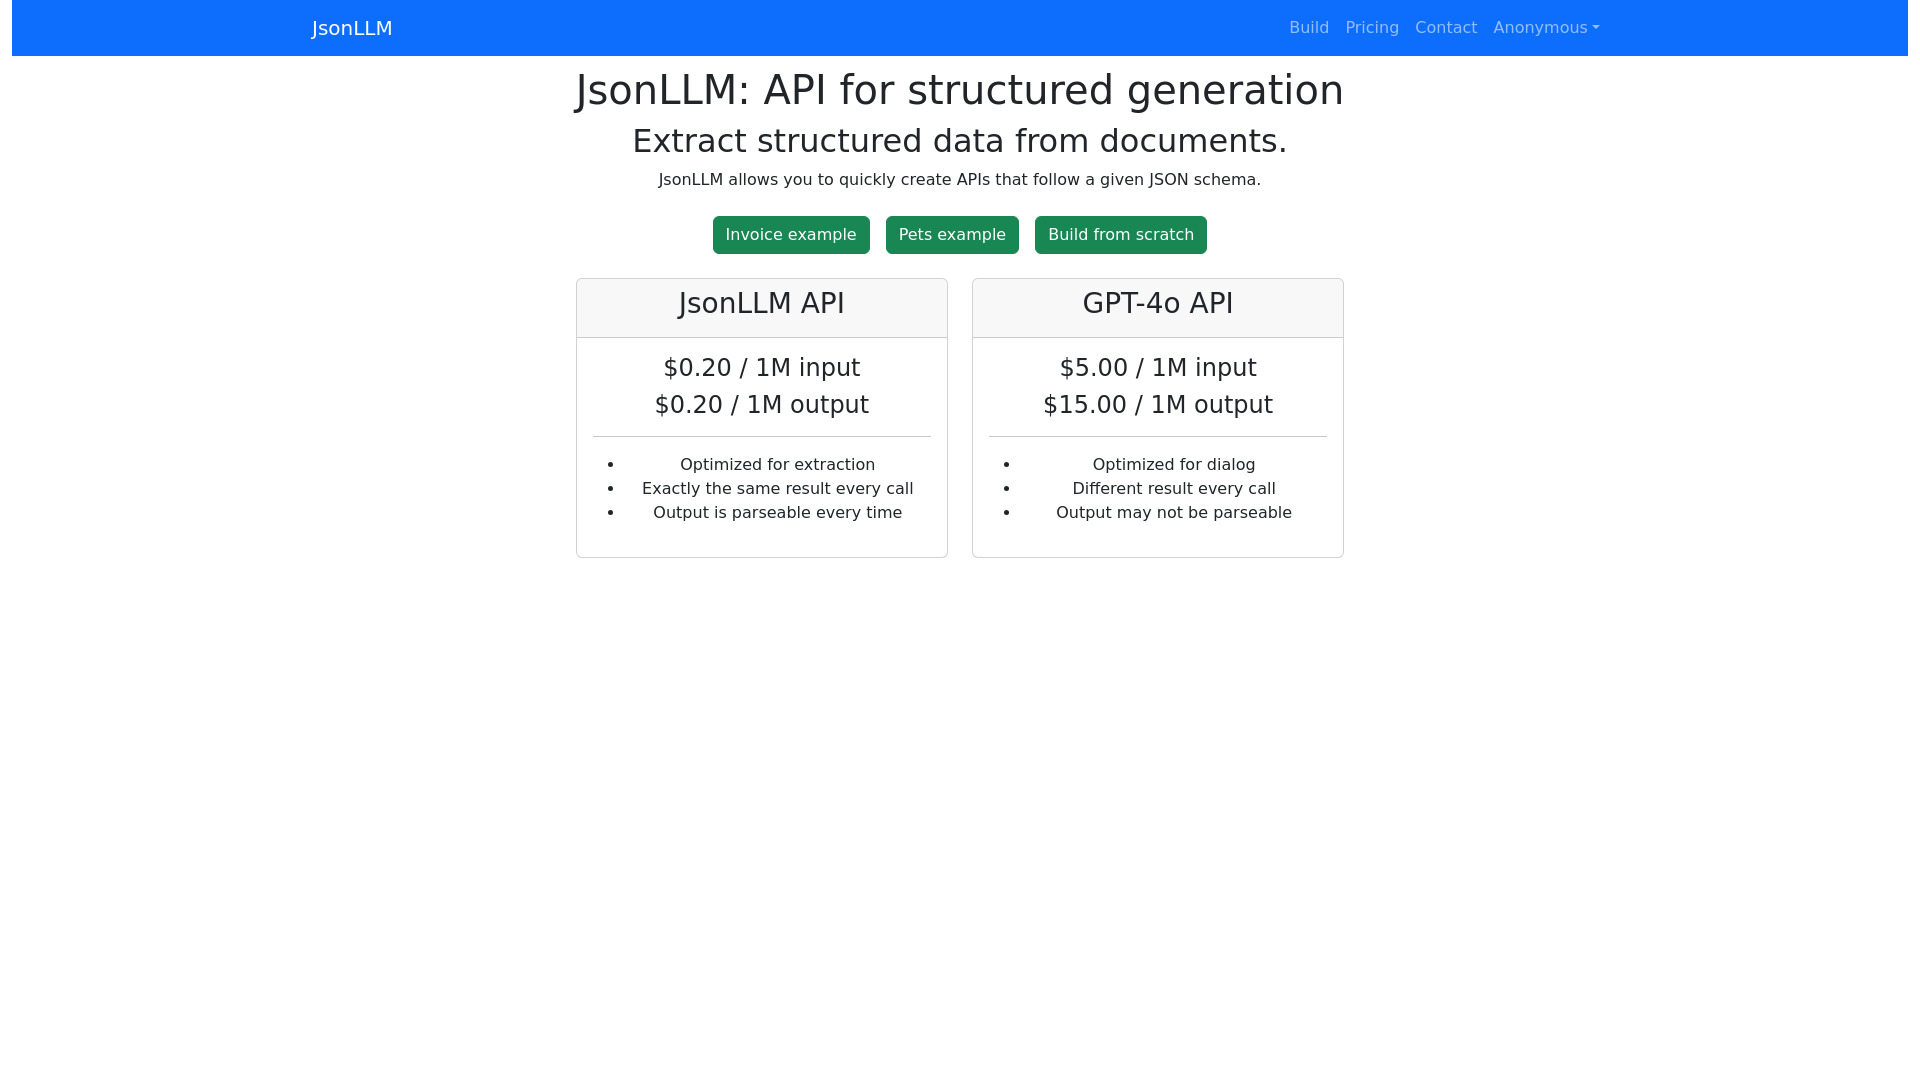
5. JsonLLM

- Data scientists creating structured extraction APIs
- Free plan available
- Starts at Check vendor pricing
- Usage signal: Not listed
Why it matters
JsonLLM takes a direct route from an output schema to a usable API. It can create APIs from JSON schemas and extract structured data from PDFs and text documents, which is exactly the kind of constraint many annotation projects need. Instead of asking a model for an open-ended summary, you define the shape of the answer and inspect whether the returned fields are consistent. Its stated cost advantage over GPT-4 is appealing, but buyers should validate current economics with their own document volume and accuracy requirements.
Best for
Data scientists defining repeatable fields for unstructured documents
Teams that need extracted data in JSON rather than prose
Developers turning document workflows into quick APIs
Limitations
The product provides less detail about broader workflow and review controls
Field accuracy still depends on the source material and model behavior
Pricing and usage terms should be confirmed directly with the vendor
Shortlist signal: Shortlist JsonLLM when schema consistency and API-ready extraction are the central success criteria.
6. ThirdAI

- Enterprises deploying private GenAI on CPUs
- Free plan available
- Starts at Check vendor pricing
- Usage signal: Not listed
Why it matters
ThirdAI belongs on this list for teams whose annotation data cannot casually leave their environment. It offers enterprise SSO, built-in models, and a no-code interface while focusing on completely private, air-gapped deployment. The ability to run on CPUs can also change the infrastructure conversation for organizations that cannot or do not want to depend on expensive GPUs. This is more deployment platform than labeling application, but deployment constraints often determine which data workflows are feasible in the first place.
Best for
Enterprises handling sensitive or regulated data
Teams that need air-gapped GenAI deployment
Organizations evaluating CPU-based model infrastructure
Limitations
Initial setup and configuration may take time
Performance can vary with the available CPU infrastructure
Pricing is hidden behind a vendor conversation rather than a clear public starting point
Shortlist signal: Choose ThirdAI when deployment privacy and infrastructure control are non-negotiable parts of your annotation workflow.
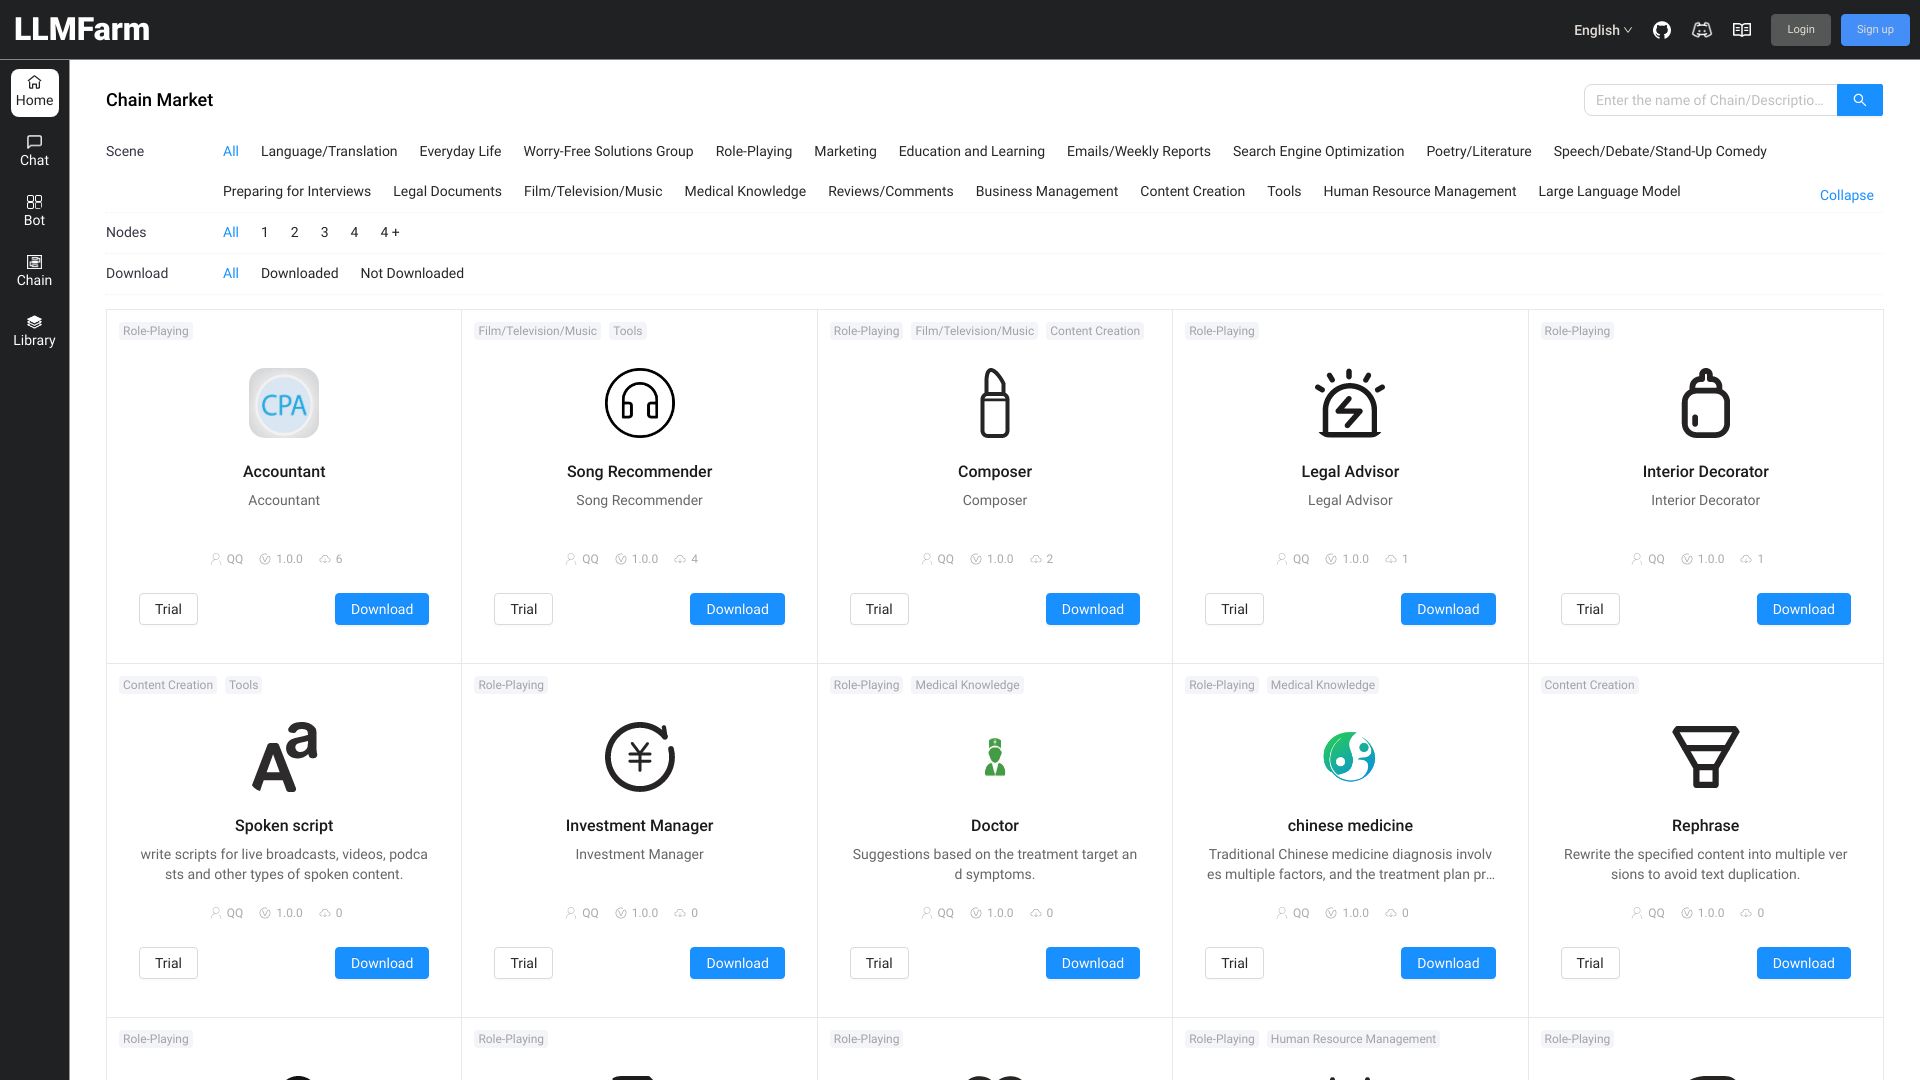
7. LLM Farm
- AI developers exploring models and reusable chains
- Free plan available
- Starts at Check vendor pricing
- Usage signal: Not listed
Why it matters
LLM Farm is useful when your project is still in exploration mode and you want access to multiple LLMs, downloadable templates, chain libraries, and PDF parsing tools in one place. That breadth can help a developer test different approaches to document handling and prompt chains before committing to a production stack. The same breadth is also the product's main challenge: it can feel like a toolbox rather than a guided annotation workflow.
Best for
AI developers comparing multiple LLM options
Prototypers who want templates and chain libraries
Teams experimenting with PDF parsing and model integrations
Limitations
The interface may feel overwhelming because of the number of tools
Some capabilities require specific technical knowledge
Buyers may need to assemble their own repeatable review process
Shortlist signal: Add LLM Farm when breadth and experimentation matter more than a tightly managed annotation experience.
8. LLM-X.AI
- Software developers integrating LLMs through one API
- Free plan available
- Starts at Check vendor pricing
- Usage signal: Not listed
Why it matters
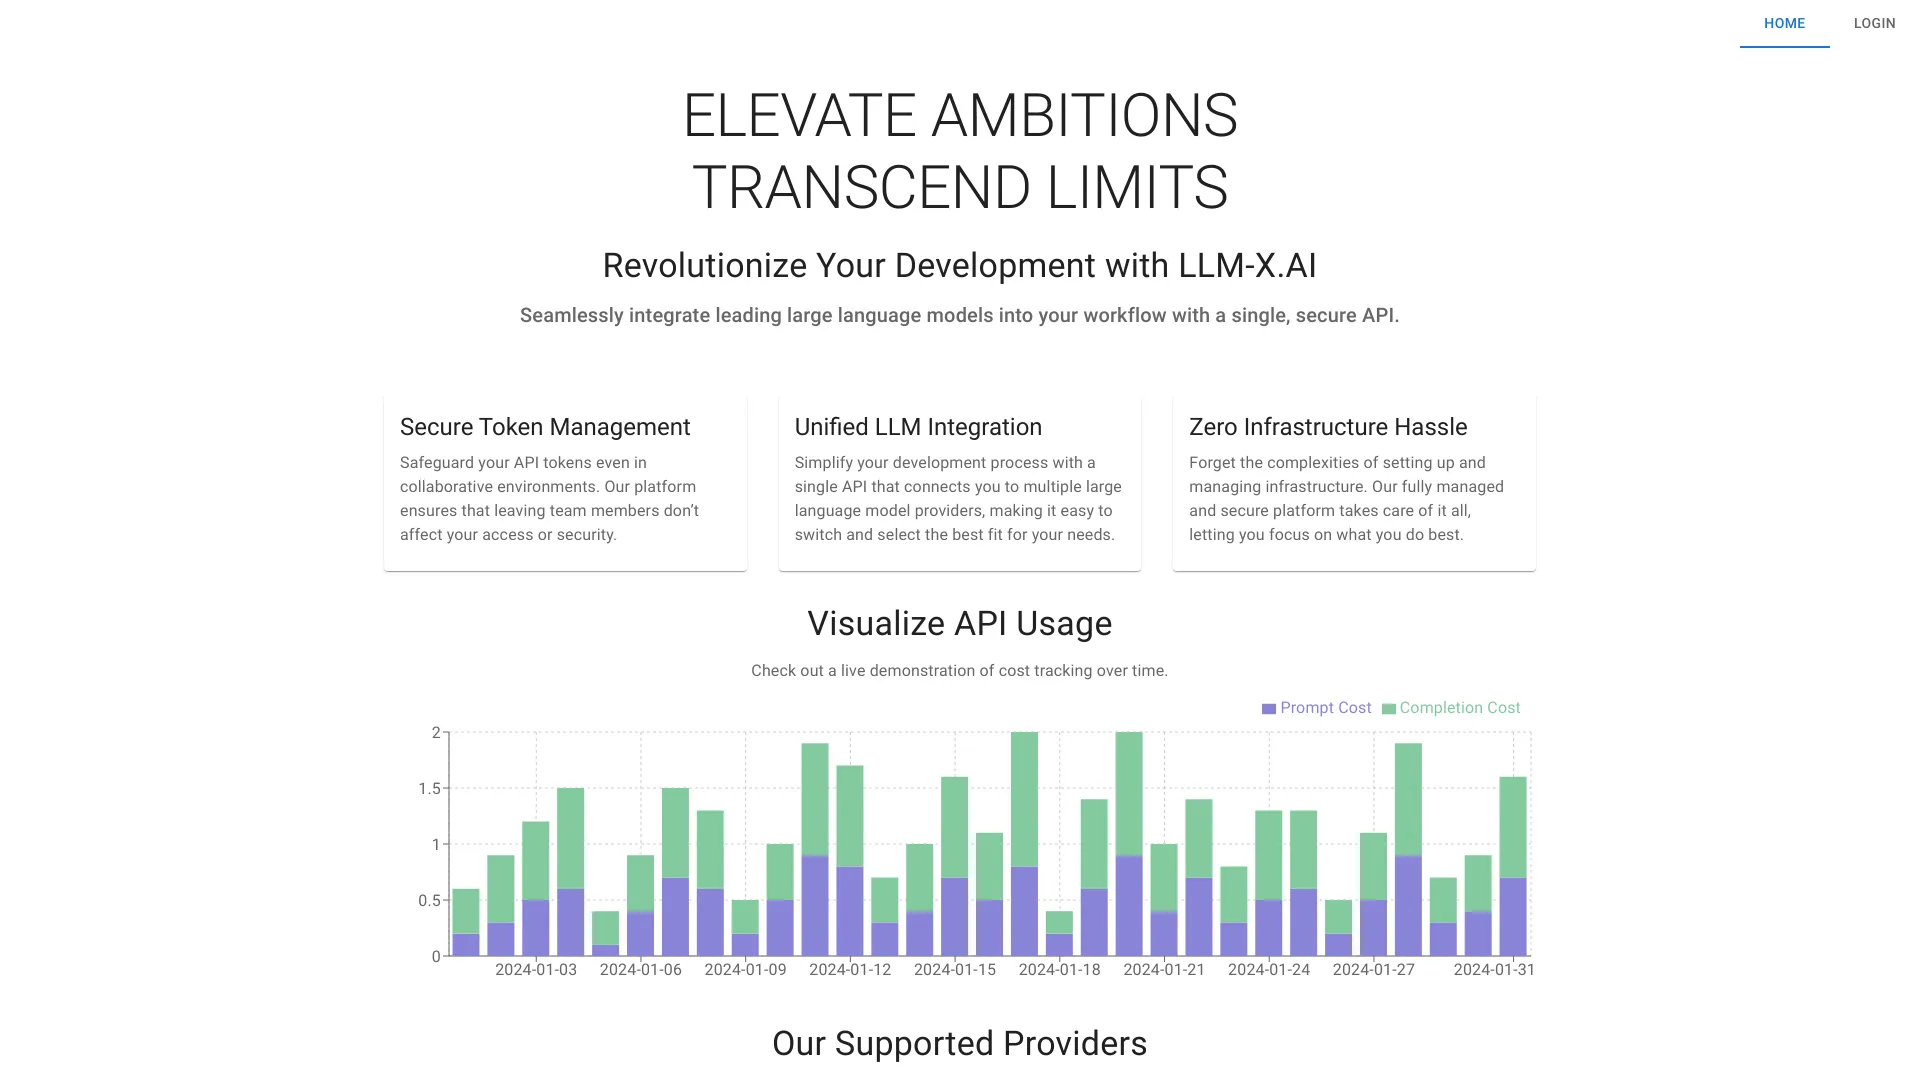
LLM-X.AI focuses on the plumbing that often surrounds an annotation or evaluation system: secure token management, unified LLM integration, and less infrastructure hassle. A single API can simplify experiments that compare prompts or model outputs, particularly for a small development team. It does not replace a document labeling workspace, but it can reduce the effort required to connect an application to model services while keeping credentials organized.
Best for
Software developers building LLM-enabled applications
Teams that want a unified integration layer
Projects that need secure API token management
Limitations
You rely on LLM-X.AI for model access
Usage costs may vary with the selected service and volume
Custom integrations still require technical knowledge
Shortlist signal: Consider LLM-X.AI when integration and credential management are blocking progress on your LLM data workflow.
9. LLM Tester

- AI developers evaluating conversational systems
- Free plan available
- Starts at Basic: $59 per month
- Usage signal: Not listed
Why it matters
LLM Tester is the most direct choice here for teams that need to check whether an LLM system behaves as intended. Automated LLM evaluation, comprehensive analytics, and custom test scenarios create a repeatable way to probe conversational AI instead of relying on informal spot checks. That makes it valuable after annotation guidelines or structured datasets have been created: you can use the resulting scenarios to test the application against known expectations. The price is more visible than many tools on this list, but the setup still favors technical users.
Best for
AI developers testing conversational applications
QA teams creating custom model scenarios
Teams that need analytics around repeated LLM evaluations
Limitations
Pricing may be a barrier for smaller projects
Custom integrations require technical knowledge
It evaluates systems rather than providing a traditional labeling interface
Shortlist signal: Shortlist LLM Tester when proving quality through repeatable scenarios matters more than manually tagging source text.
10. LLM Clash
- AI enthusiasts comparing model behavior
- Free plan available
- Starts at Check vendor pricing
- Usage signal: Not listed
Why it matters
LLM Clash offers a simple idea with practical value: let models debate or respond against one another in real time. It supports fine-tuned, local, or cloud-hosted LLMs, so it can help a team notice differences in tone, reasoning, or response quality before choosing a model for a larger workflow. It is not a replacement for systematic annotation or an evaluation suite, but side-by-side comparison can be a useful early filter when the team is still deciding which models deserve deeper testing.
Best for
AI enthusiasts comparing model responses interactively
Teams testing fine-tuned, local, and cloud-hosted models
Early-stage model selection and prompt exploration
Limitations
JavaScript is required to run the site
Information about specific features is limited
Real-time debates should supplement, not replace, a formal evaluation plan
Shortlist signal: Use LLM Clash when quick model comparison will help you decide which systems deserve structured testing.
What to test before choosing
A convincing demo can hide the exact friction that determines whether a tool survives contact with a real dataset. Run a small, representative pilot before committing.
- 1
Document variety: Test clean PDFs, scanned pages, tables, long reports, and documents with inconsistent formatting. A tool that works on one pristine sample may fail on the material your team actually receives.
- 2
Output structure: For extraction workflows, define required fields in advance. Check whether missing values, ambiguous passages, and repeated entities are handled consistently.
- 3
Human review: Ask a reviewer to correct outputs and record how much cleanup each document requires. Fast extraction is not useful if every field needs a manual rewrite.
- 4
Privacy and deployment: Confirm whether data is processed locally, sent to a hosted service, or available in an air-gapped configuration. This distinction matters more than a generic privacy label.
- 5
Repeatability: Run the same input more than once where possible. Compare whether the output remains stable enough for training data, retrieval, or evaluation.
- 6
Integration effort: Measure the steps needed to export JSON, connect an API, store results, or hand work to another reviewer. Setup friction becomes expensive at scale.
- 7
Cost at volume: Use your expected document count, page count, credits, model calls, and reviewer time. Free access is useful for testing, but it rarely predicts production cost on its own.
What to do next
Start with the workflow, not the product name. Write down whether your first milestone is extracting fields, reviewing documents, creating a knowledge base, testing conversations, or deploying an application privately. Then select one tool from the matching segment and run a controlled pilot with 20 to 50 representative items.
For a broad first test, use AnythingLLM or DocumentLLM to understand the human review experience. If the output must feed software, compare LlamaIndex with JsonLLM. If the application already exists and quality is the concern, test LLM Tester before investing in a larger annotation process. Teams with strict infrastructure requirements should move ThirdAI higher in the queue, even if its deployment evaluation takes longer.
Keep a simple scorecard with extraction accuracy, reviewer time, setup hours, export quality, privacy fit, and estimated monthly cost. That evidence will tell you more than a generic feature checklist. Once the winner is clear, verify current pricing and contract terms with the vendor before moving sensitive data or building around a proprietary workflow.
Common mistakes when choosing from a complex top list
Expecting every tool to be a labeling platform: Several options here support annotation-adjacent work such as parsing, extraction, RAG, and evaluation. Confirm that the tool supports your exact labeling action before buying.
Confusing document chat with ground-truth creation: Chat can surface useful information, but a training dataset still needs defined labels, review rules, and quality checks.
Ranking by traffic alone: A popular local workspace may be less suitable than a smaller evaluation tool for a production QA team.
Ignoring the reviewer experience: Developer flexibility does not automatically create a comfortable process for legal, operations, or research reviewers.
Treating free access as a production plan: Check quotas, document limits, credits, storage, model access, and export restrictions.
Skipping difficult examples: Test ambiguous, incomplete, multilingual, scanned, and unusually long inputs before trusting a workflow.
Forgetting deployment constraints: A hosted tool may be convenient, while an air-gapped or local option may be mandatory for your data.
Assuming model comparison equals evaluation: Side-by-side responses are useful for discovery, but robust evaluation needs repeatable scenarios and defined success criteria.
FAQ
AnythingLLM is the strongest overall match for local document work, RAG, and agents. LlamaIndex is better for production-oriented parsing and extraction pipelines, while DocumentLLM suits interactive document review. For structured output, JsonLLM is the more focused choice, and LLM Tester is the better fit for evaluating the resulting application.