Start here
Searching for top-rated human-in-the-loop annotation tools for nlp should lead you to platforms for labeling text, managing annotators, resolving disagreements, and checking annotation quality. This 10-tool comparison needs an important qualification: the products surfaced here do not establish those capabilities. Most focus on AI text rewriting, model access, language learning, or other workflows. None can be responsibly recommended from the listed features as a dedicated human-in-the-loop NLP annotation platform.
That distinction is useful rather than a reason to force a match. If you are researching an NLP pipeline, some of these products may help with adjacent tasks: checking generated text, studying language, routing model requests, or organizing research. But they are not substitutes for an annotation environment with task queues, labeling guidelines, reviewer roles, adjudication, export formats, and quality controls. We rank the ten listed products by their stated use cases and explain where the fit stops, so you can avoid buying an adjacent tool for the wrong job.
Quick recommendation: For text rewriting, start with Clever AI Detector or PaperBleach. For language-learning analysis, consider LingTube. For a team AI assistant, look at OpenTag. If your requirement is actual human annotation of NLP data, keep this list as an adjacent-tools reference and verify annotation-specific workflows with vendors before shortlisting.
Segment comparison
| Segment | Tools to inspect | What they appear suited to | Annotation fit |
|---|---|---|---|
| AI text rewriting and detection | Clever AI Detector, PaperBleach, SmartHumanizer | Rewriting or checking generated prose | Not established |
| Language and customer research | LingTube, Dilog | Video-based language study or interview-grounded feedback | Adjacent only |
| Team and developer AI workflows | OpenTag, LLMFly AI, ML.ai | Team assistance, model access, or coding tasks | Not established |
| Research organization and evaluation | Flexnote, AI Humanizer Benchmark | Personal knowledge organization or humanizer comparisons | Not annotation platforms |
The key divide is between tools that work with language and tools that manage human labeling. NLP exposure alone does not make a product an annotation system. For production labeling, ask whether a tool supports the complete review loop, not simply whether it processes or rewrites text.
Shortlist paths
| Your immediate need | Start with | Why it may fit | Check before committing |
|---|---|---|---|
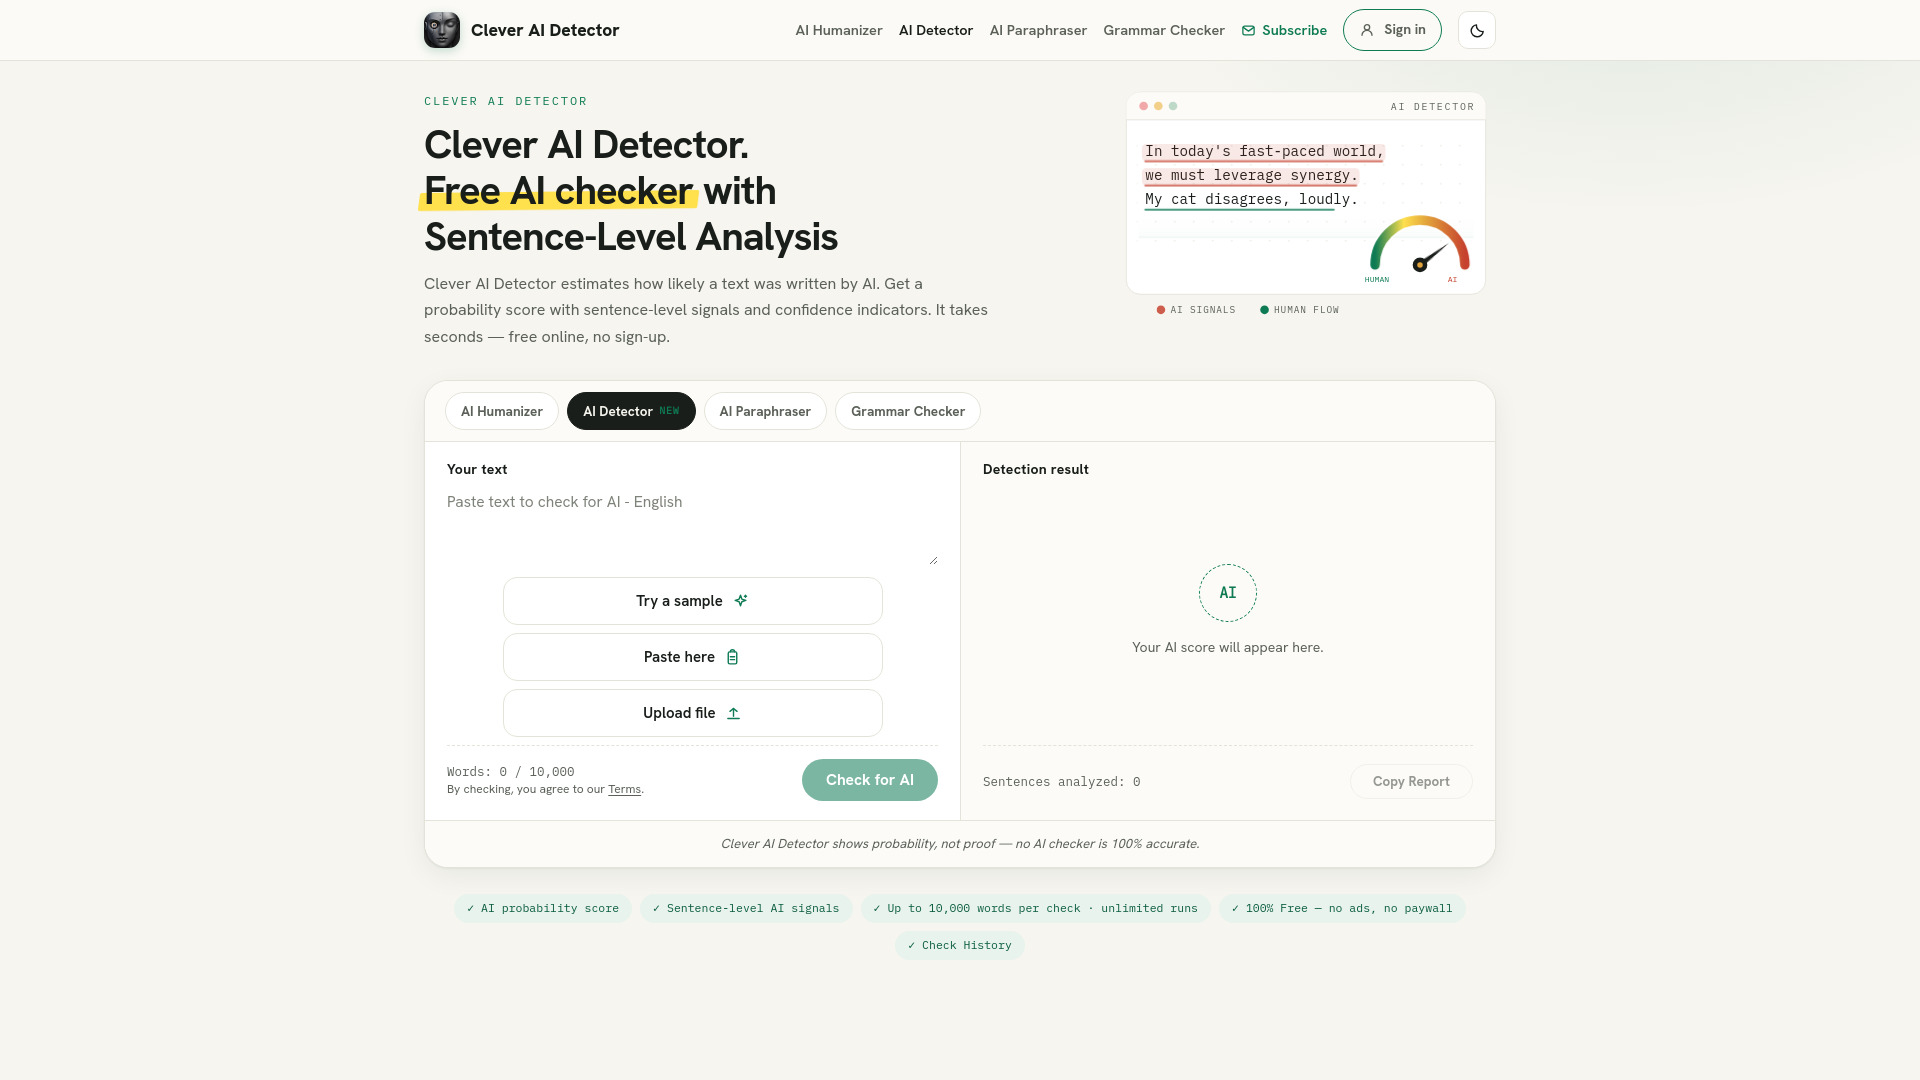
| Rewrite or polish AI-generated prose | Clever AI Detector | Free text humanization and a 3,000-word request limit | Whether its rewriting workflow is appropriate for your policy and use case |
| Pair rewriting with a detector | Humanizer - PaperBleach | Offers a humanizer and built-in detector | English-only support and the 2,500-word request limit |
| Learn from subtitled video | LingTube | Dual subtitles and context-aware translation for YouTube and Netflix | Chrome requirement and limited free AI access |
| Give a team an AI coworker | OpenTag | Team conversations, model routing, and listed integrations | Trial card requirement and monthly credit reset rules |
| Label and adjudicate NLP examples | None established in this list | The described features do not show annotation queues or review controls | Find a vendor that demonstrates the full labeling workflow |
That last path is the one that matters most for this keyword. If a vendor cannot show how a label moves from an annotator to quality review and final adjudication, do not infer that workflow from AI features or a text editor.
Ranking snapshot
This snapshot groups the ten products by their strongest stated use, rather than implying that rank equals annotation suitability. The supplied scores are product-ranking signals, not evidence of NLP labeling performance.
| Rank | Tool | Score | Strongest stated angle |
|---|---|---|---|
| 1-2 | Clever AI Detector, Humanizer - PaperBleach | 92, 91 | Free rewriting; rewriting with a built-in detector |
| 3-4 | OpenTag, Flexnote | 90, 90 | Team AI coworker; visual research notes |
| 5-6 | LingTube, Dilog | 89, 89 | Video language learning; interview-grounded customer feedback |
| 7-8 | LLMFly AI, SmartHumanizer | 88, 88 | Multi-model API access; one-click rewriting |
| 9-10 | ML.ai, AI Humanizer Benchmark | 87, 87 | Coding agent; comparative humanizer testing |
How we grouped and ranked the list
We organized these products around the workflows their stated features actually describe. That means the list includes text rewriting and detection, language learning, customer research, team AI assistance, model access, note-taking, coding, and humanizer benchmarking. Those segments can sit near an NLP program, but they are not interchangeable with an annotation platform.
For a true human-in-the-loop annotation shortlist, the critical evidence would include a way to create labeling tasks, assign human annotators, present consistent guidelines, capture labels, review disagreements, adjudicate edge cases, and export usable datasets. You would also want to inspect access controls, auditability, data handling, and support for the data types and label schema you use. None of those capabilities is established by the product facts available for these ten tools, so we do not award any of them a direct annotation-fit claim.
Within the adjacent set, the ordering reflects the provided scores and each product's stated strength, audience, limitations, and market signal. A score is not a substitute for workflow fit. A high-ranked text humanizer can be a sensible pick for rewriting prose and still be the wrong choice for labeling intent, sentiment, entities, or relations across a dataset. Treat the ranking as a guide to adjacent tasks, then validate any product against your actual requirements.
We also distinguish products from evidence about products. For example, a benchmark that evaluates humanizers may help you compare rewriting tools, but it is not itself a labeling workspace. A visual note canvas may help a researcher organize observations, but that does not establish multi-annotator review or dataset export. The field notes below spell out those boundaries instead of stretching the category to make every entry sound like a direct match.
Ranked field notes
1. Clever AI Detector
- Writers polishing AI-generated prose
- Up to 3,000 words per request; no sign-up; $0
- Starts at Free: $0
- Usage signal: 5.9M
Why it matters
Clever AI Detector is the strongest pick here for a straightforward writing workflow, not for annotating NLP data. It is free to use, accepts requests up to 3,000 words, and focuses on improving tone, sentence structure, clarity, and readability while reducing repetitive phrasing. Preserving the original meaning is a practical aim when editing drafts, although the result can vary with the source text. Its large usage signal makes it the most visible option in this group, but popularity does not demonstrate labeling, reviewer management, or dataset export. Use it to polish prose; do not treat a rewrite as a human-verified annotation.
Best for
Writers refining shorter AI-generated passages.
Users who want a no-cost rewriting workflow without a fixed monthly word allowance.
Teams exploring readability improvements on text, separately from dataset labeling.
Limitations
Requests are capped at 3,000 words.
Output quality can vary depending on the source text.
No stated annotation queues, labeling schema, or review process make it a poor fit for human-in-the-loop data operations.
Shortlist signal: Add Clever AI Detector when your real need is free, short-form text polishing; exclude it from a shortlist that requires annotation management.
2. Humanizer - PaperBleach

- Students checking and rewriting English text
- Free AI humanizer and detector
- Starts at 7-day premium access: $4.99
- Usage signal: 90.0K

Why it matters
PaperBleach pairs an AI text humanizer with a built-in detector, giving users a rewrite-and-check loop in one product. It accepts content generated by ChatGPT, Claude, and Gemini, and the site promotes free access to both the humanizer and detector. That combination is useful for checking how a passage changes after rewriting, but it should not be mistaken for human annotation or a dependable label-quality workflow. The English-only limitation and 2,500-word request cap are important if you process multilingual content or long documents. The listed $4.99 offer is for seven days of premium access, so check the vendor's current terms before relying on it as ongoing pricing.
Best for
Students who want a rewriting tool and detector in the same workflow.
English-language passages generated with common AI assistants.
Users comparing a source passage with a revised version.
Limitations
English is the only stated supported language.
The 2,500-word limit may interrupt work on longer documents.
Detector and rewriting functions do not establish annotator review, adjudication, or labeling exports.
Shortlist signal: Shortlist PaperBleach for English text rewriting plus a built-in detector, not for labeling NLP datasets.
3. OpenTag
- Operations teams coordinating AI-assisted work
- 7-day free trial; payment card required
- Starts at Trial: $0
- Usage signal: 34.6K
Why it matters
OpenTag approaches AI through team conversations: its AI coworker answers questions and performs tasks, while model-agnostic routing selects a model for each task. Integrations listed include GitHub, Stripe, Zendesk, Notion, and PostHog, which gives operations teams a way to bring AI assistance into familiar tools. Shared workspace credits are a notable alternative to per-seat charging, but monthly credits reset; only signing-bonus credits do not expire. This is useful infrastructure for team AI tasks, not an annotation system. The product facts do not establish a labeling interface, human review stages, or controls for resolving conflicting labels.
Best for
Operations teams that want an AI coworker in team conversations.
Groups that prefer task-based model routing over choosing a model manually.
Teams using the listed services and willing to evaluate a card-required trial.
Limitations
A payment card is required to start the seven-day free trial.
Recurring monthly credits reset at the end of the month.
No stated annotation-specific workflow supports using it as a dataset labeling platform.
Shortlist signal: Consider OpenTag for shared AI assistance across team tasks, and only consider it for annotation if the vendor can demonstrate the complete labeling and review workflow you need.
4. Flexnote

- Researchers organizing connected notes
- 3 whiteboards and 100 cards
- Starts at Free: $0
- Usage signal: 19.3K
Why it matters
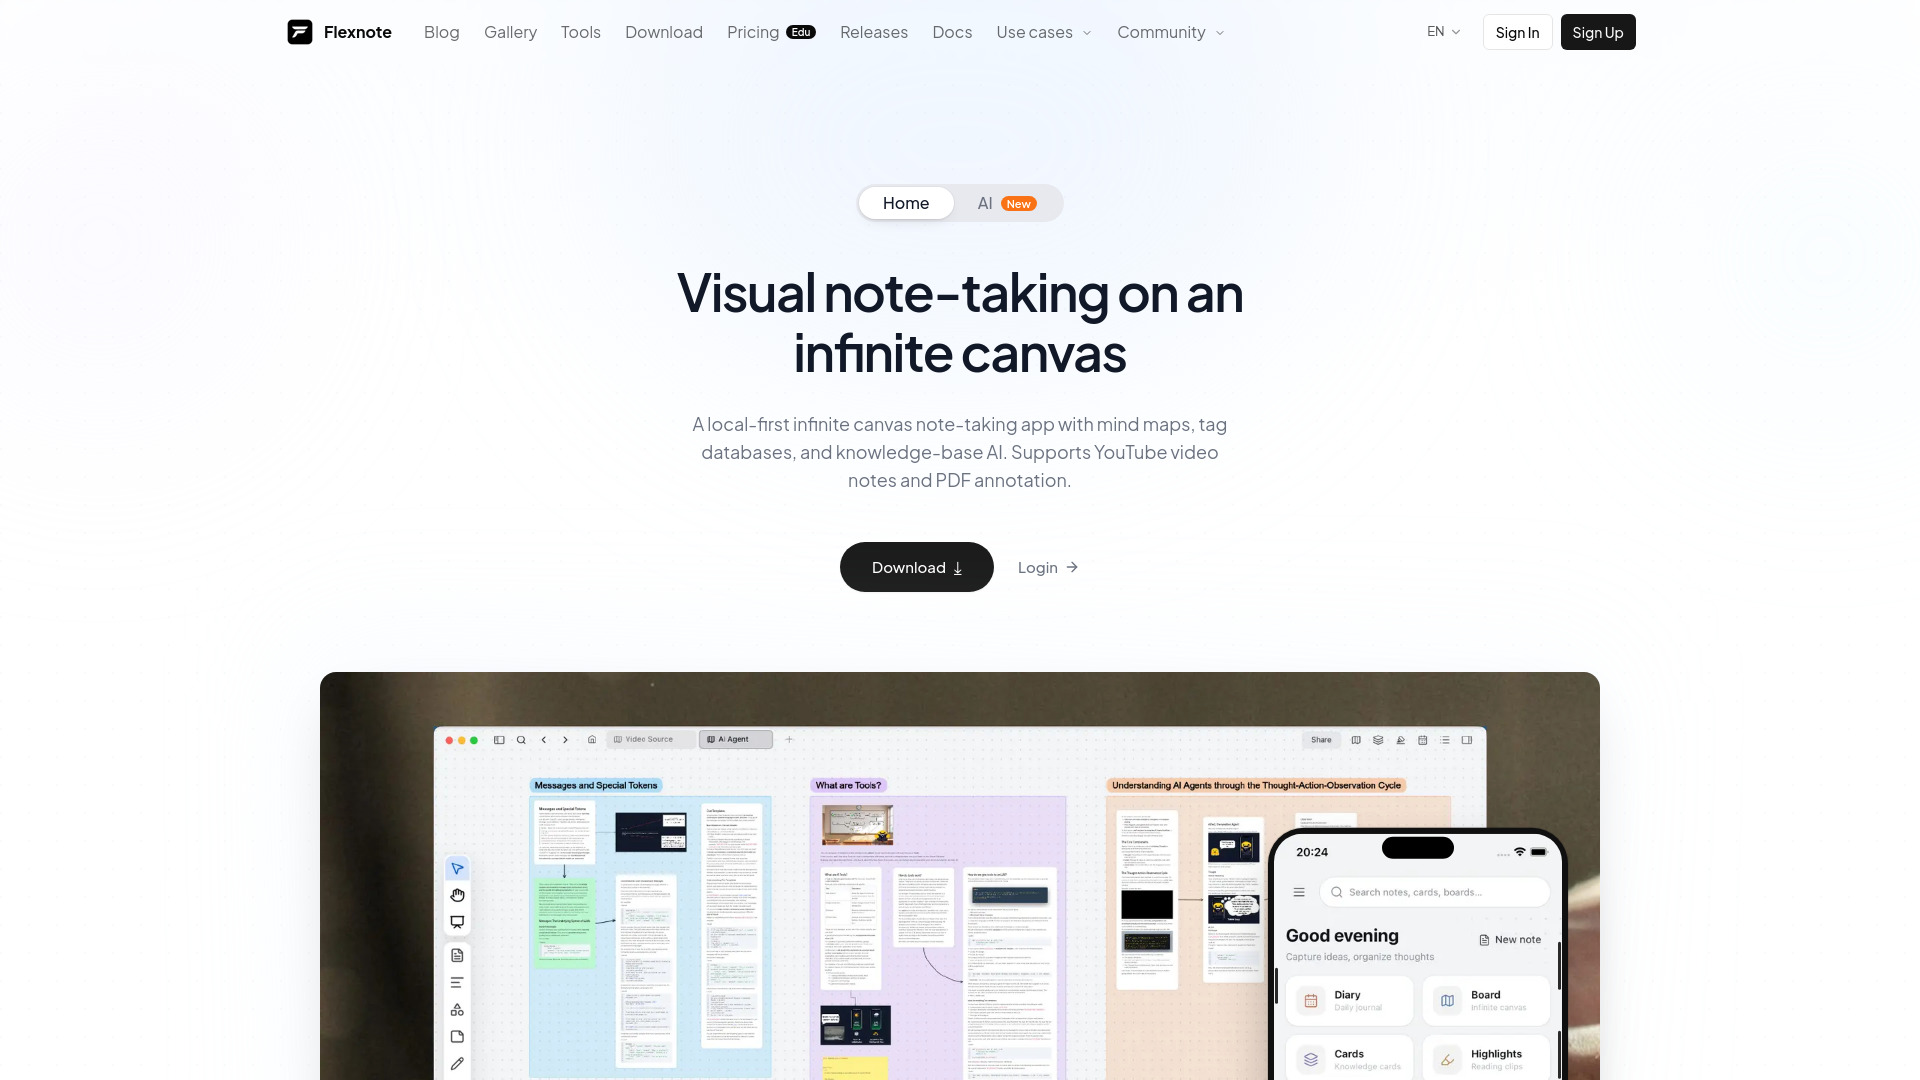
Flexnote gives researchers a visual place to arrange and connect ideas: cards support Markdown and bidirectional links, while an infinite canvas can be viewed as a mind map. It also supports offline editing and stores notes locally by default, which may suit a solo researcher collecting observations. The free plan's three-whiteboard and 100-card limits give you a defined way to try the workflow. Still, a knowledge canvas is not a substitute for an annotation queue. The listed features do not establish multiple annotator roles, shared labeling guidelines, adjudication, or structured dataset exports. Cloud sync and multi-device support also require a paid plan.
Best for
Researchers collecting and connecting notes during exploratory work.
Users who prefer a visual canvas, Markdown cards, and mind-map views.
People who value local-first storage and offline editing.
Limitations
The free plan stops at three whiteboards and 100 cards.
Cloud sync and multi-device support require a paid plan.
The described knowledge-management features do not prove support for team annotation or dataset production.
Shortlist signal: Add Flexnote for personal research organization; do not choose it as a labeling platform without confirming collaboration, review, and export features directly.
5. LingTube

- Language learners studying subtitled video
- 3-day Premium upon registration
- Starts at Free: $0
- Usage signal: 873
Why it matters
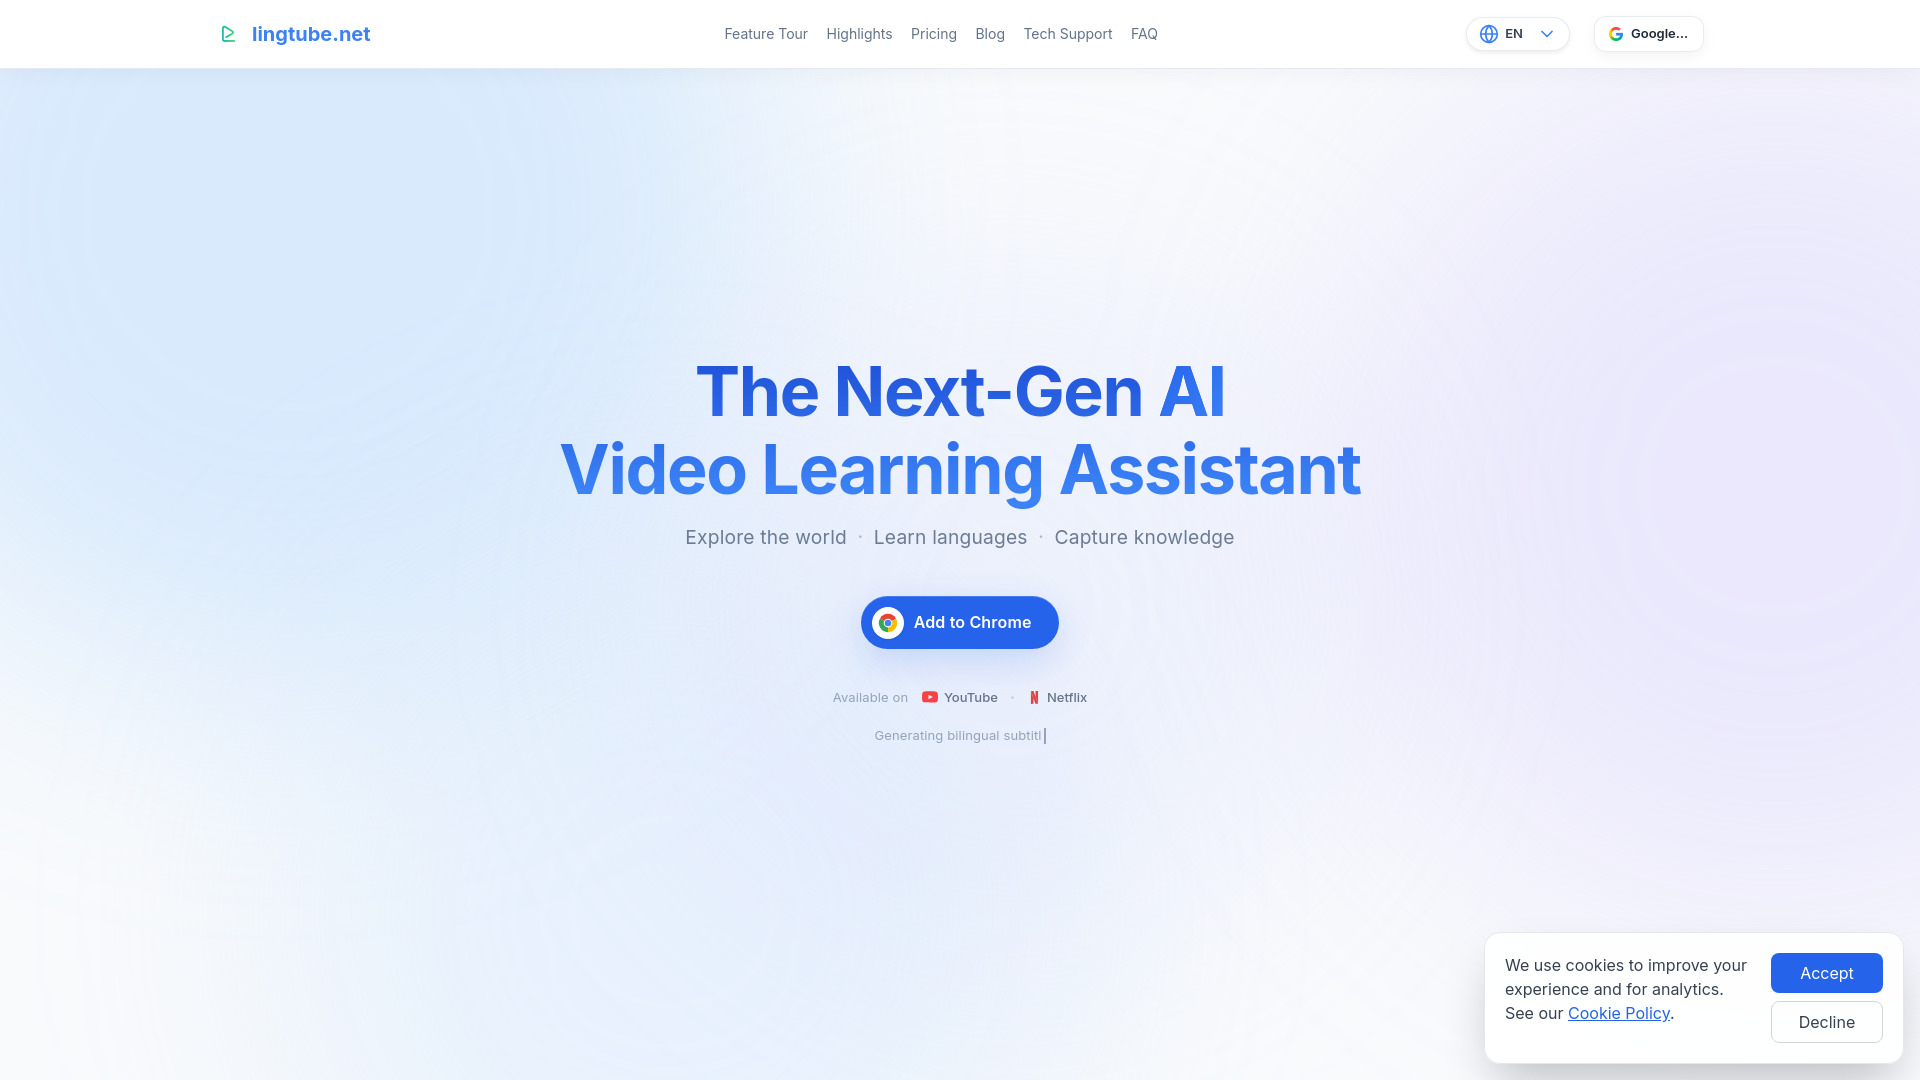
LingTube puts language-learning tools alongside video playback, with dual subtitles for YouTube and Netflix and context-aware translation for words and phrases. Its subtitle analysis includes part-of-speech tagging, plus language-specific supports such as furigana and pinyin. That makes it an interesting adjacent option for someone studying language in context; it does not make it a general-purpose human annotation product. The workflow requires a Chrome extension and is aimed at two video services, while free access to AI features is limited compared with paid plans. It is most relevant when your data source is video and your goal is learning, not when you need scalable text labeling.
Best for
Language learners studying through YouTube or Netflix.
Viewers who benefit from bilingual subtitles and contextual word translation.
Learners working with language-specific reading aids such as furigana or pinyin.
Limitations
Requires a Chrome extension and is intended for YouTube and Netflix.
Free-plan access to AI features is limited compared with paid plans.
The product description does not establish project-level annotation, quality review, or dataset export.
Shortlist signal: Shortlist LingTube for supported video-based language study, not for building or adjudicating an NLP training corpus.
6. Dilog
- Product managers seeking interview-grounded feedback
- 14-day free trial
- Starts at $50-$125 AUD/month for individual tiers
- Usage signal: 341
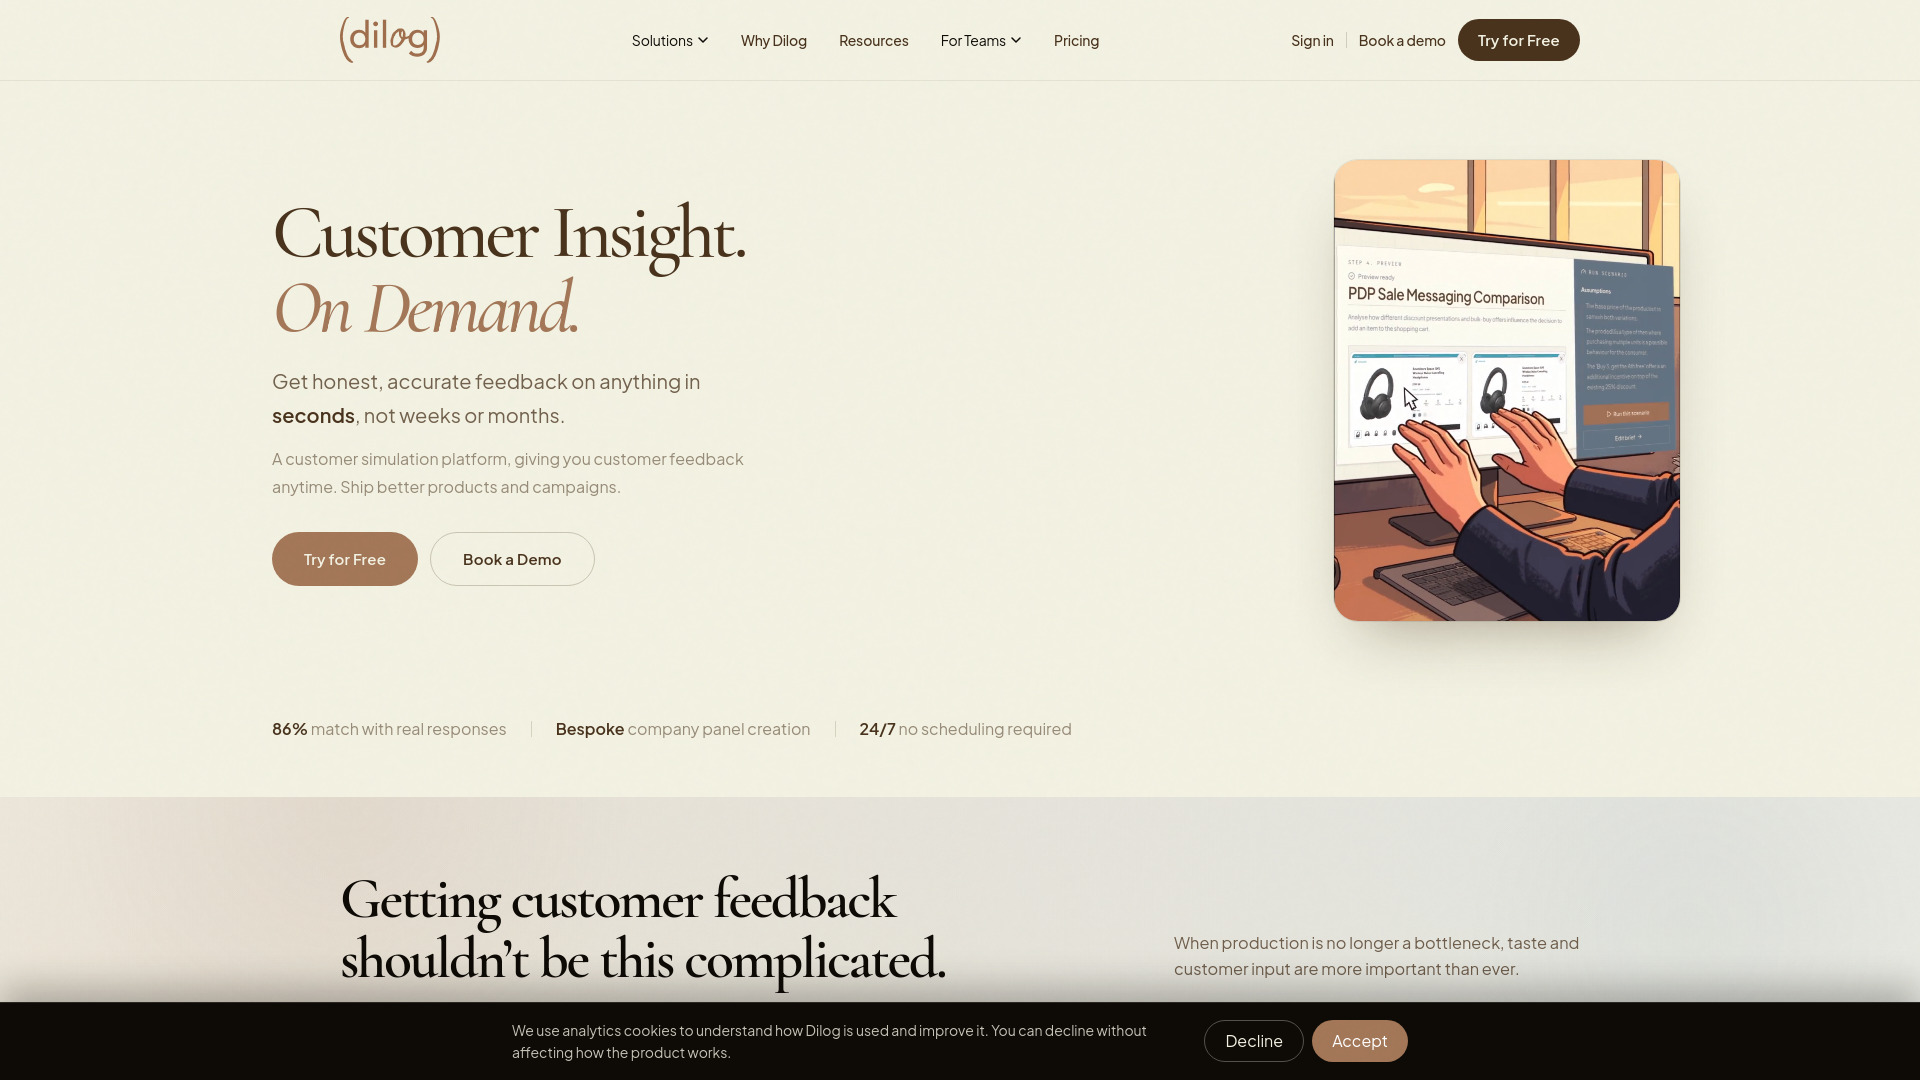
Why it matters
Dilog is built around customer simulation informed by long-form interviews with real customers. For product managers, that can help explore likely reactions to ideas or changes faster than waiting weeks or months for feedback. The distinction matters: customer simulation is not the same as having human annotators label NLP examples, and the stated features do not show an annotation workspace. Individual tiers are listed at $50-$125 AUD per month depending on question volume, while bespoke organizational panels require a roughly six-to-twelve-week setup and separately scoped pricing. A 14-day trial gives you a chance to test the research workflow, but not a basis for assuming labeling capabilities.
Best for
Product managers exploring customer responses to potential changes.
Teams that want feedback grounded in long-form interviews with real customers.
Buyers evaluating an individual tier before requesting a bespoke panel.
Limitations
Bespoke organizational panels take approximately six to twelve weeks to set up.
Business panel setup costs are scoped separately and are not listed publicly.
Customer feedback simulation does not establish annotation assignment, review, or export functions.
Shortlist signal: Consider Dilog for interview-grounded product research; ask for a separate demonstration if you need human labeling of NLP data.
7. LLMFly AI
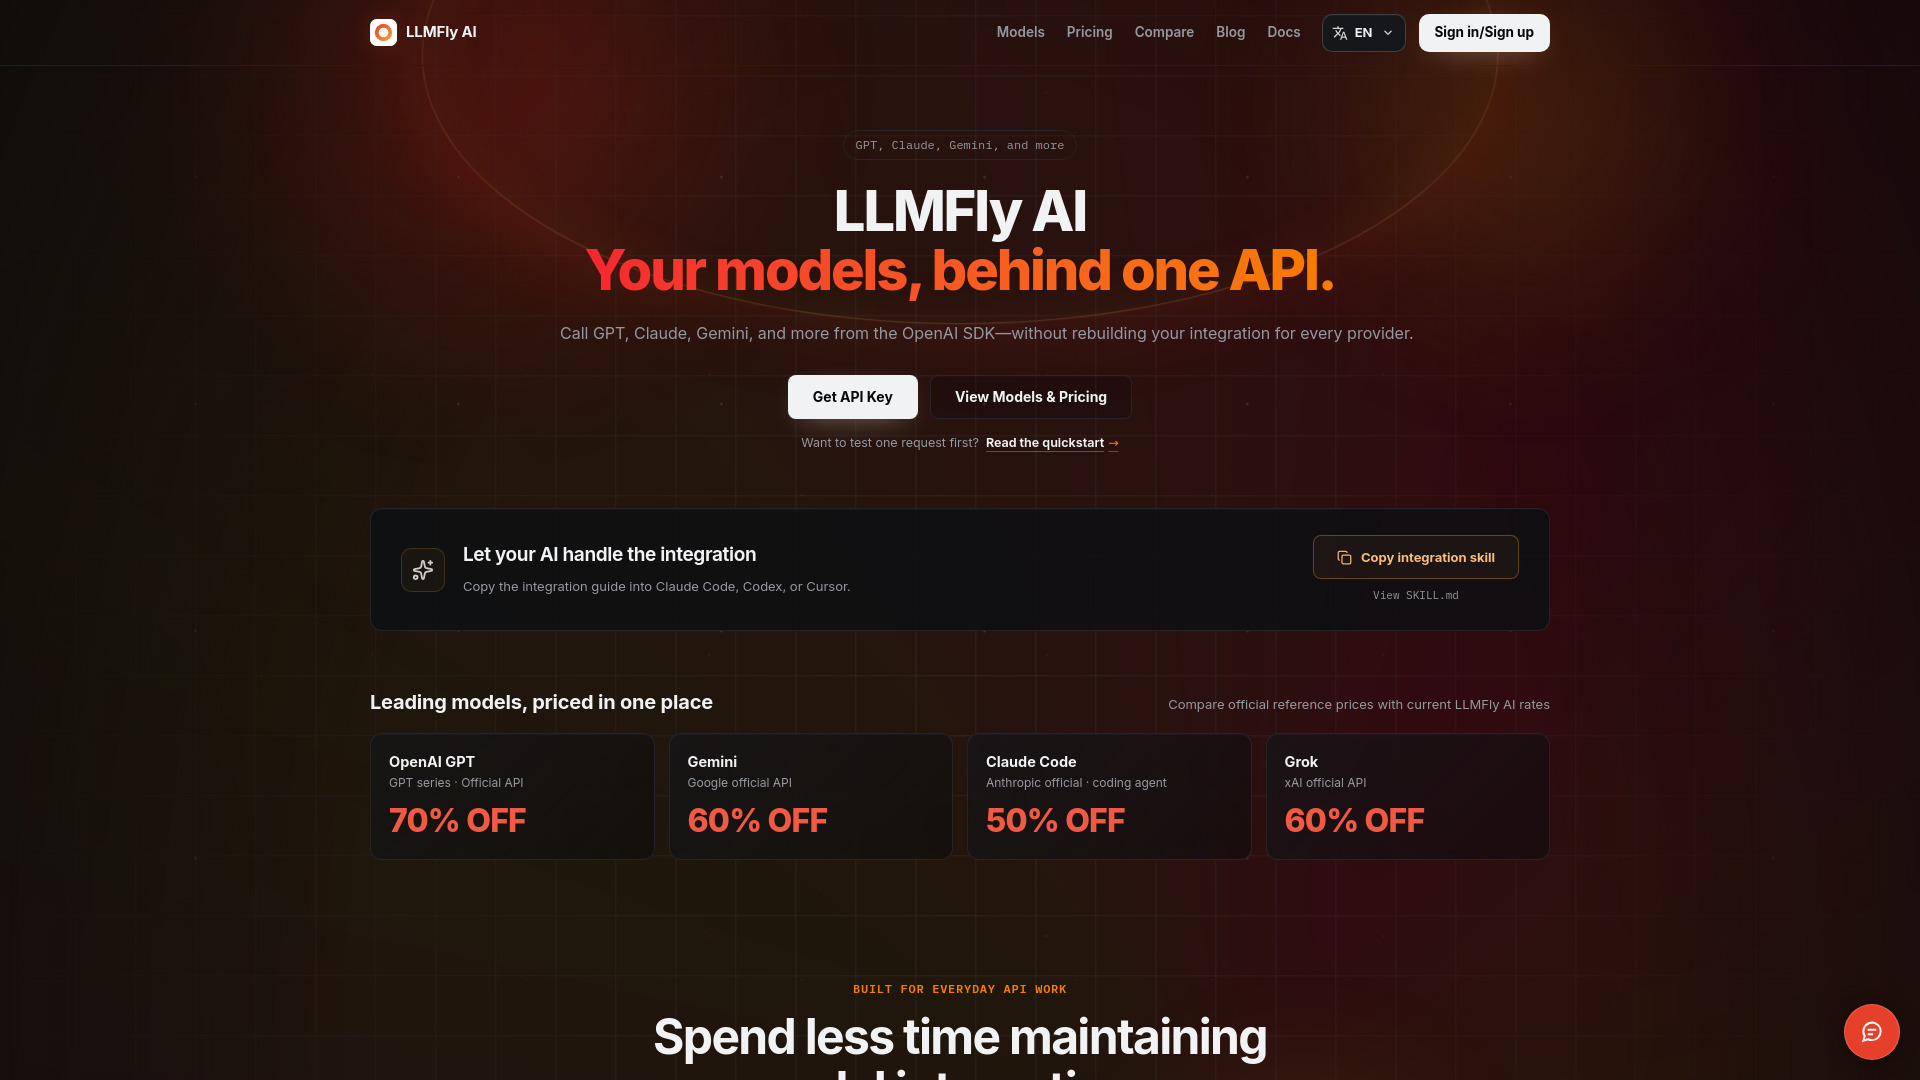
- Developers accessing multiple AI model providers
- Starts at Check vendor pricing
- Usage signal: 71
Why it matters
LLMFly AI is aimed at developers who want one OpenAI-compatible API for models from providers such as GPT, Claude, Gemini, and Grok. A centralized catalog lists input, output, and cache pricing, and API keys can be managed for separate applications and environments. That can simplify model access in an NLP application, but it does not add human annotation to the workflow. Model availability can change, and provider list prices do not necessarily match LLMFly's charges. Pricing is not clear enough to quote a starting amount here, so verify the current commercial terms and model catalog before building around it.
Best for
Developers who want a common API pattern across multiple model providers.
Teams managing API keys across separate applications or environments.
Builders who want model and token-pricing information in a centralized catalog.
Limitations
Actual model availability can change.
Provider list prices may not equal LLMFly AI charges.
API access is not evidence of human labeling, adjudication, or annotation quality controls.
Shortlist signal: Add LLMFly AI when your problem is multi-model API access, not when your project needs a human-in-the-loop annotation interface.
8. SmartHumanizer
- Students rewriting generated text
- Free use is mentioned; allowance unclear
- Starts at Plus: $12/month
- Usage signal: Not listed
Why it matters
SmartHumanizer centers on a one-click rewrite rather than a multi-step editing process. Its stated aim is to improve clarity, flow, and sentence rhythm while preserving intended meaning, tone, quotes, citations, and references. That preservation claim makes it worth examining for students revising text with references, but the free usage allowance is not clearly specified and larger monthly volumes or advanced workflows require paid plans. As with the other writing tools here, changing prose is not the same as assigning labels to examples and checking those labels with human reviewers. Keep the distinction especially clear if your NLP workflow depends on traceable, reproducible annotations.
Best for
Students looking for a simple text-rewriting workflow.
Users who want a tool that says it preserves citations and references.
Buyers comfortable evaluating a $12-per-month Plus plan for higher-volume needs.
Limitations
The free usage allowance is not clearly specified.
Paid plans are required for larger monthly word volumes and advanced workflows.
Text rewriting does not establish human annotation, review history, or structured labeling output.
Shortlist signal: Consider SmartHumanizer for one-click prose refinement, and rule it out for annotation unless the vendor demonstrates annotation-specific controls.
9. ML.ai

- Developers delegating software tasks
- Starts at Check vendor pricing
- Usage signal: Not listed
Why it matters
ML.ai is described as a coding agent spanning an IDE extension, desktop app, PR reviewer, and CLI, with shared settings and repository memory. Its focused agents handle exploration, architecture, planning, and general work; only the general agent can change code. Reviewable diffs and approval controls are the useful checks here, alongside cost-aware model routing. But this is a software-development workflow, not an NLP annotation tool. The product is described as being in private beta, India first, and individual pricing may change at general availability. Treat it as an early-stage coding option, not infrastructure for human labeling.
Best for
Developers who want an agent to carry software tasks through code changes and testing.
Teams that prefer to inspect diffs and approve changes before they are written.
Users evaluating a private-beta product across IDE, desktop, pull-request, and CLI surfaces.
Limitations
The product is described as private beta, India first.
Individual plan prices are private-beta launch pricing and may change.
Coding agents and approval diffs do not establish annotation queues or human-label review.
Shortlist signal: Put ML.ai on a coding-agent shortlist only if its beta access and region fit; do not treat it as an annotation platform.
10. AI Humanizer Benchmark
- Content writers comparing humanizer results
- Starts at UndetectedGPT paid plan: $19.99/month
- Usage signal: Not listed
Why it matters
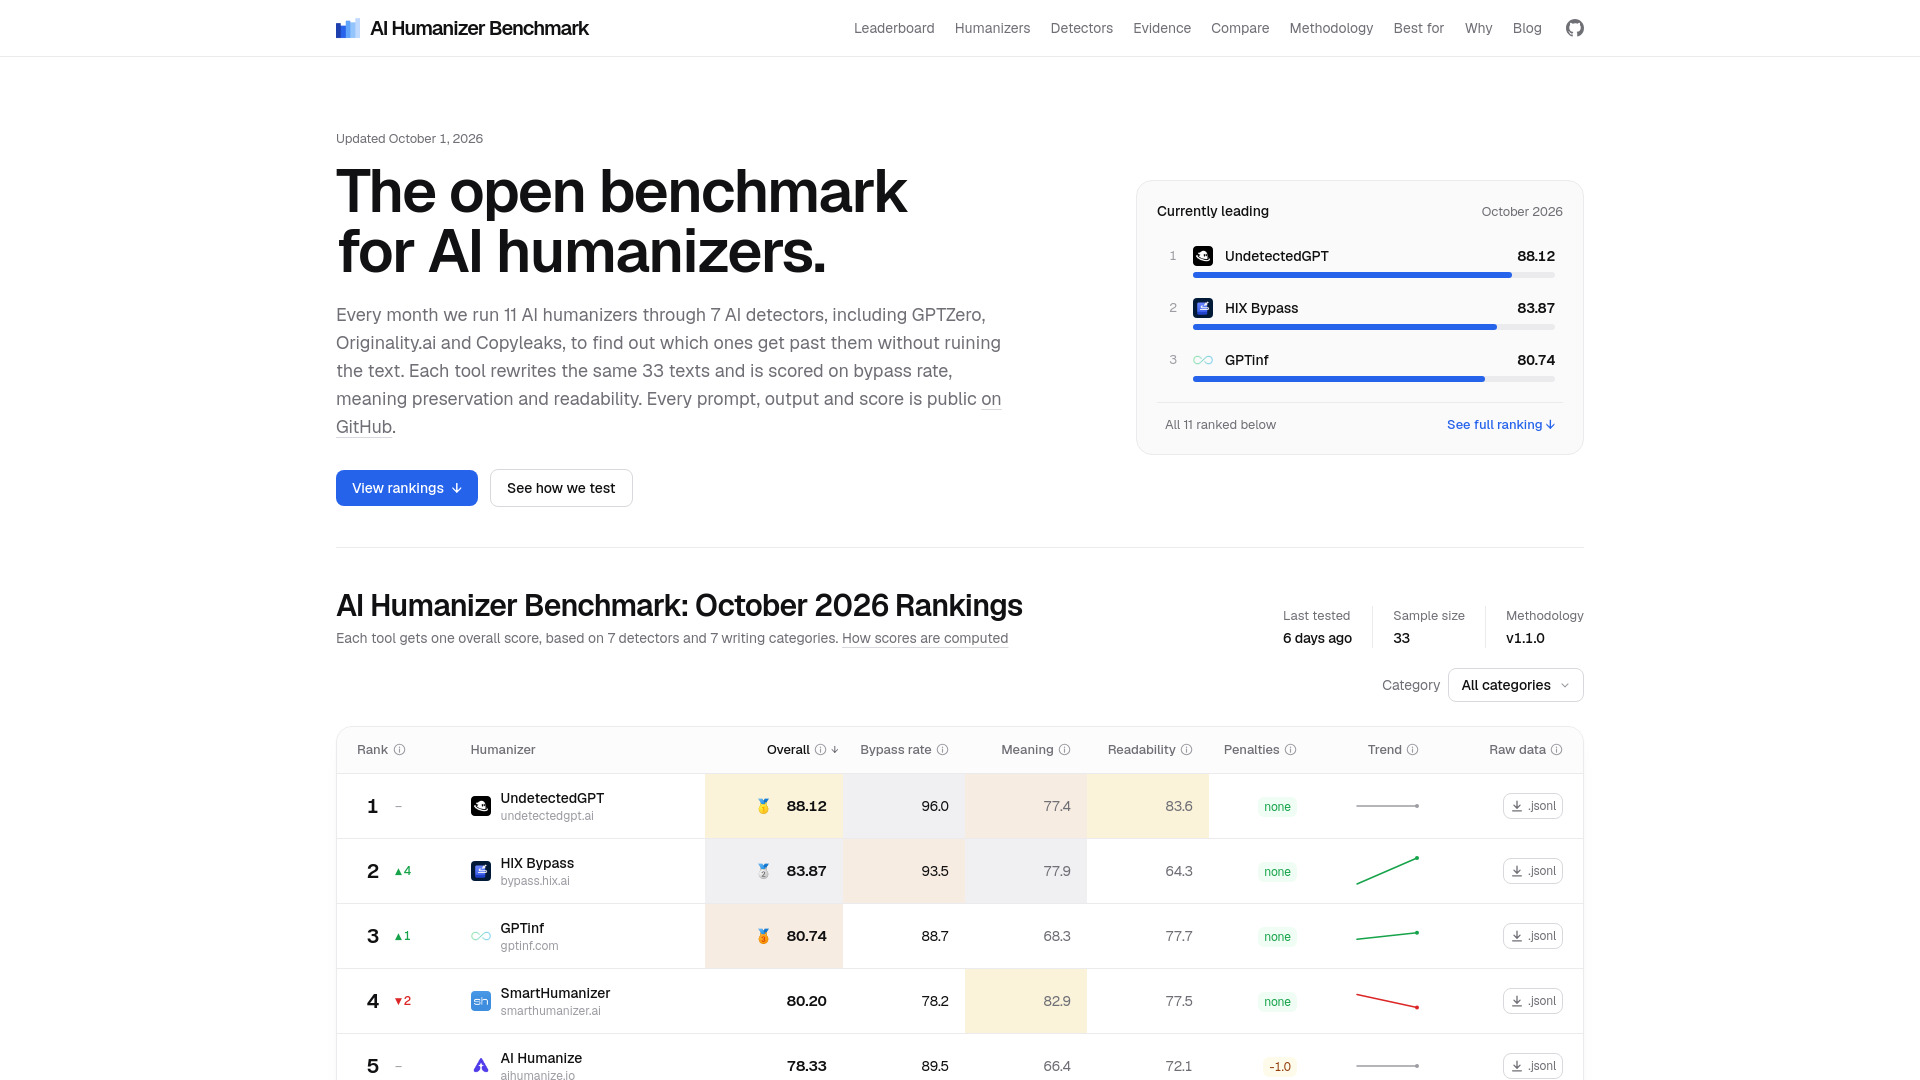
AI Humanizer Benchmark is an evaluation resource, not a text-labeling product. It reports monthly comparisons using the same texts and default settings, tests results across seven detectors, and scores detector bypass, meaning preservation, readability, and consistency. Public raw data and a stated methodology can help content writers inspect how a benchmark was assembled. There is a meaningful caveat: the benchmark is operated by a team whose own product, UndetectedGPT, is included in its rankings. Its results also reflect a sample of 33 texts, which may not predict how other writing performs. The $19.99-per-month figure refers to UndetectedGPT's lowest paid plan, not a clearly stated price for the benchmark itself.
Best for
Content writers comparing AI humanizer performance across a shared test set.
Readers who want to inspect raw data and the scoring methodology.
People who value results across several detectors rather than a single detector.
Limitations
The benchmark operator also ranks its own product, UndetectedGPT.
Results use a sample of 33 texts and may not generalize to every passage.
Benchmarking humanizers is not the same as annotating NLP data; the listed price is for UndetectedGPT.
Shortlist signal: Use the benchmark as one source when comparing humanizers, but not as a vendor shortlist for human annotation.
What to test before choosing
For a genuine human-in-the-loop NLP annotation product, make the vendor show your workflow end to end. A polished demo is not enough; use representative examples, difficult edge cases, and the people who will actually label and review the data.
Create a task from your own data. Import a small, representative batch and check whether the tool handles your formats and label schema without awkward workarounds.
Test guideline clarity. Give annotators the same instructions and see whether examples, definitions, and edge cases are easy to consult while labeling.
Exercise disagreement handling. Ask what happens when two annotators disagree, who can adjudicate, and how the final decision is recorded.
Check quality signals. Look for a demonstrable way to review work and identify inconsistent labels; do not assume a generic AI feature supplies quality assurance.
Inspect permissions and history. Confirm who can annotate, review, export, and change guidelines, and whether teams can inspect what happened to a label.
Export a real result. Verify that the final labels, identifiers, and any needed metadata come out in a format your downstream NLP pipeline can use.
Ask about data handling. Get clear answers about access, storage, retention, and handling of your actual text before uploading sensitive material.
Price a realistic project. Ask for the cost at your expected volume, including reviewer work, setup, and any usage or seat limits that apply.
For the ten tools in this guide, test the adjacent workflow they actually claim to support: rewriting quality and word limits for humanizers, video and language coverage for LingTube, team integrations and credit rules for OpenTag, or API availability and costs for LLMFly AI. Don't let a successful test in one of those workflows stand in for an annotation pilot.
What to do next
First, write down the task you are buying for: labeling text, polishing copy, studying language, gathering customer feedback, or building an AI application. If the answer is annotation, define your label schema, project size, reviewer process, and export requirements before requesting demos. Then ask each prospective vendor to show those exact steps with your sample data.
If your need is adjacent rather than direct, use the shortlist paths above: Clever AI Detector or PaperBleach for rewriting, LingTube for video-based language study, OpenTag for a team AI coworker, and LLMFly AI for multi-model API access. Confirm current pricing and terms with each vendor. The practical takeaway is simple: choose for the workflow you need, not for the word "NLP" appearing somewhere in a product's feature set.
Common mistakes when choosing from a complex top list
Treating language-related features as annotation. Translation, rewriting, model access, and language learning do not prove that a product can manage human labels.
Assuming a high score means category fit. The scores here do not measure annotation accuracy or reviewer workflow.
Skipping the disagreement step. A labeling tool needs a credible answer for inconsistent judgments, not just a place to enter a first label.
Confusing an evaluation resource with a workbench. AI Humanizer Benchmark compares humanizers; it is not a workspace for assigning annotations.
Buying from a screenshot or general demo. Ask to test your data, guidelines, edge cases, and export path.
Treating trial access as a complete price quote. Check card requirements, credit resets, plan limits, and whether quoted prices apply to the workflow you need.
Overlooking the human part. The value of human-in-the-loop work depends on clear instructions, accountable review, and a usable record of decisions, not merely an AI feature.
FAQ
The listed product facts do not establish that any of the ten is a dedicated annotation platform. They describe tools for writing, language learning, team AI assistance, customer research, model access, notes, coding, or benchmark comparisons. Ask a prospective annotation vendor to demonstrate task assignment, labeling, review, adjudication, and export before treating it as a fit.